AI newsUpdate
Claude Fable 5.2 API price: $8 / $40, fast mode at 2x
Claude Fable 5.2 costs $8 in and $40 out per 1M tokens; fast mode doubles it. See the API id and what an agent day costs.
On this page
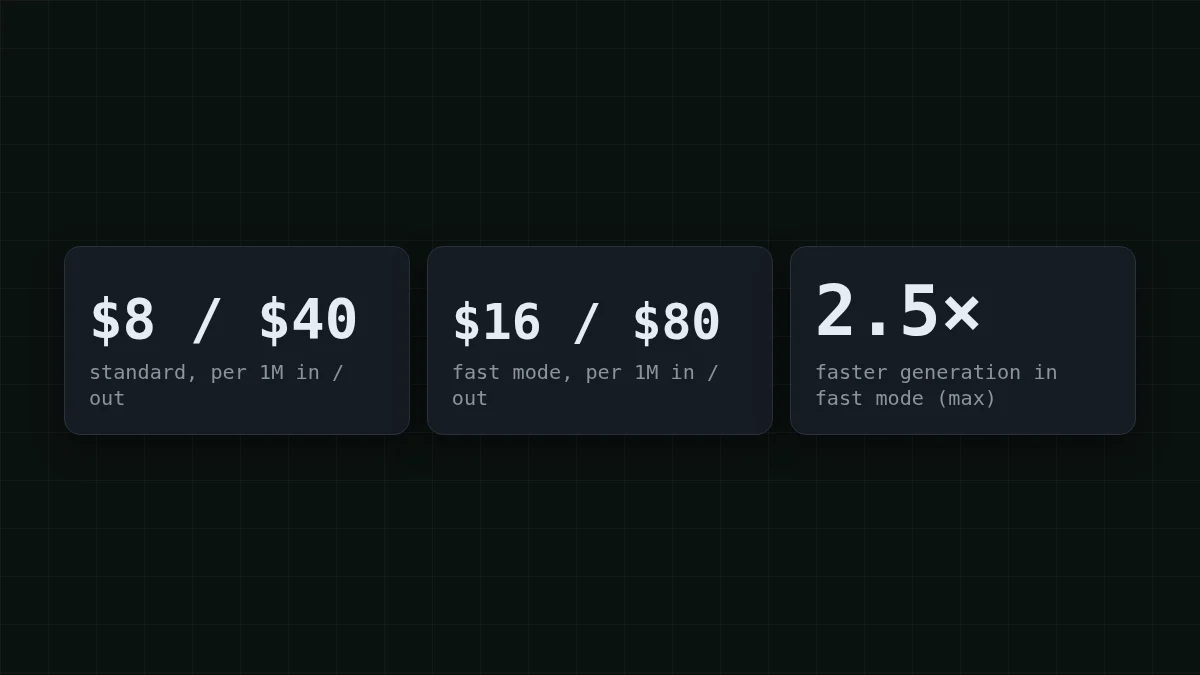
Claude Fable 5.2 is on the API as claude-fable-5-2. Standard price is $8 per 1M input tokens and $40 per 1M output tokens. Fast mode generates up to 2.5x faster and costs exactly double: $16 / $80. That's from Anthropic's release page of 9 November 2026 (checked 10 November), and the rest of this post is about what those numbers do to a bill.
Your agent ran for ten minutes, and the bill is bigger than the task. That's the usual story with a top-tier model in a loop, so let's put real numbers on it.
What Anthropic announced#
The release page, Claude Fable and Mythos 5.2, says:
- Fable 5.2 is available now on the Claude Platform and on AWS, Google Cloud and Microsoft Azure.
- Output is up to 30% faster than Claude Fable 5.1 (Anthropic's own claim).
- Fast mode is available in Claude Code, the Claude Platform, Claude Models on Google Cloud and Microsoft Foundry.
- Mythos 5.2 is the same underlying model with weaker restrictions, limited to organisations approved through the Cyber or Life Sciences Verification Programs. Fable has stronger cybersecurity and biology safeguards and is open to all users.
The page doesn't give the context window or the maximum output length, and I'm not guessing them here. Check them in the Anthropic docs before you size a prompt.
What one agent step costs on Fable 5.2#
Say your coding agent makes a typical middle-of-the-task call: 30,000 tokens in (the history it re-reads every step, plus tool output) and 2,000 tokens out.
- Input: 30,000 / 1,000,000 × $8 = $0.24
- Output: 2,000 / 1,000,000 × $40 = $0.08
- One step: $0.24 + $0.08 = $0.32
That looks small. Now the loop: an agent that takes 200 steps in a day costs $0.32 × 200 = $64 at the standard price. In fast mode it is $0.64 × 200 = $128 for the same work.
Notice where the money goes: three quarters of each step is the input side, the history being re-read. If you've never seen why that happens, why AI agents use so many tokens walks through a 20-step example.
Guess the number
One agent step with 30,000 tokens in and 2,000 out on Fable 5.2 at the standard price: how many cents?
Your guess
0100
Show answer
Answer: 32
32 cents: $0.24 for input plus $0.08 for output. Fast mode would double it to 64.
Is fast mode worth double?#
Fast mode changes the speed, not the answer: same model, up to 2.5x faster generation, twice the price per token. Whether that's worth it depends on who is waiting.
Pick your case
Where do you run Fable 5.2?
Choose an option to see the answer
I sit in front of Claude Code
You read each reply and decide the next move, so waiting is the expensive part. Fast mode is aimed at exactly this. Turn it on for the stretches where you're actively steering and off when you step away.
The agent runs unattended
Nobody is watching the clock, so you'd pay double for speed no one uses. Stay on the standard price, and look at which steps really need a top-tier model at all.
One caution on the arithmetic: "up to 2.5x faster" is Anthropic's ceiling, not a promise for every request. Time one of your own tasks in both modes before you decide.
Where a cheaper model fits#
Most loops are not one hard problem. They're a few hard decisions wrapped in many routine steps: read a file, run a command, summarise the output. Those routine steps don't need the priciest model, and that's where a day's cost piles up.
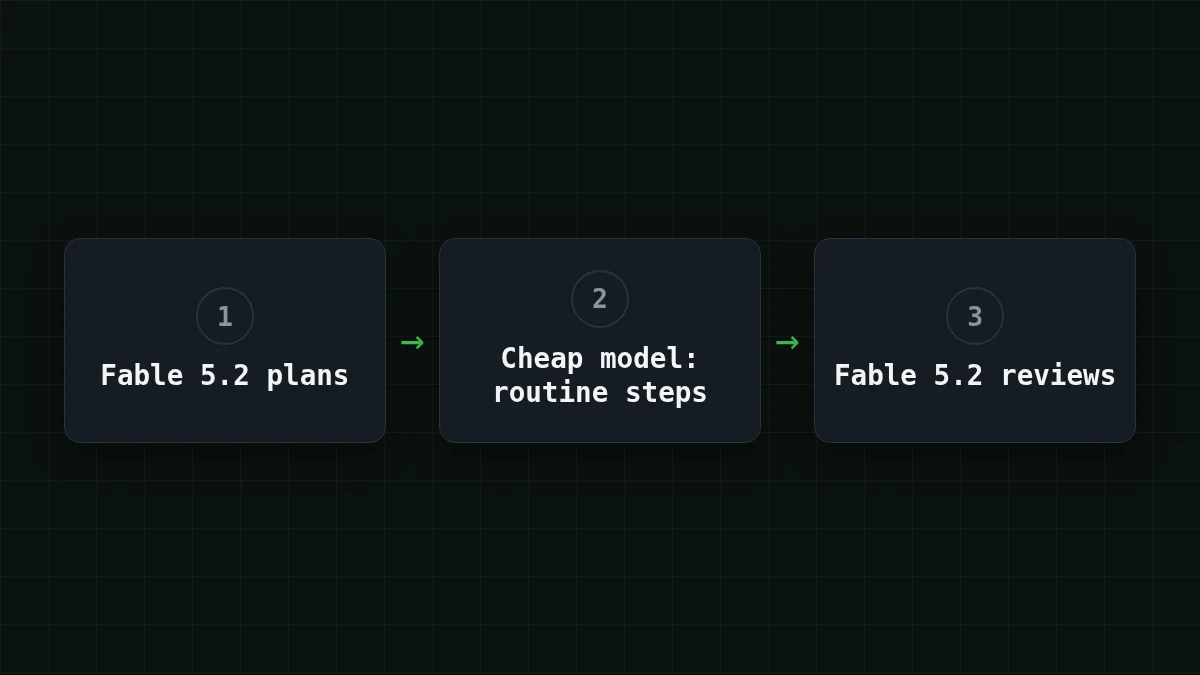
A common split is to let Fable 5.2 plan and review, and send the routine calls to a cheap model. For that role, CheapTokens has DeepSeek-V4-Flash: up to 32,768 tokens per answer, 380K context, one price at any hour, and an OpenAI- and Anthropic-compatible API. Run a few of your own routine steps on it and read usage in the reply: that shows what a step really costs you.
Here is the same 30,000-in, 2,000-out step on it: $0.00065. And the 200-step day, live from the current prices:
| Model | Input $/1M | Output $/1M | Per request | 200 requests | OpenRouter, 200 requests |
|---|---|---|---|---|---|
| GLM-5.3-Flash | $0.02 | $0.04 | $0.00068 | $0.136 | $0.234 |
| DeepSeek-V4-Flash | $0.015 | $0.10 | $0.00065 | $0.13 | $0.476 |
| MiniMax-M2.7 | $0.05 | $0.15 | $0.0018 | $0.36 | $4.32 |
30,000 input and 2,000 output tokens per request. Prices per 1M tokens are current and change together with our tariffs; the OpenRouter column shows reference prices for the same workload.
The request is a normal chat call. Use the full model id from the CheapTokens docs (deepseek-); the short id from price labels is not accepted by the API.
curl https://api.cheaptokens.dev/v1/chat/completions \
  -H "Authorization: Bearer $CHEAPTOKENS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "deepseek-ai/DeepSeek-V4-Flash-0731",
    "messages": [{"role": "user", "content": "Summarise this test output in 3 lines: ..."}],
    "max_tokens": 300
  }'
The reply has a usage block with prompt_tokens and completion_, so you can price your own steps instead of trusting my 30,000 / 2,000. Setup is in the docs, the models are on the DeepSeek page, and model routing: cheap first, escalate covers how to decide which step goes where. For Claude Code specifically, see how to make Claude Code cheaper.
Check your understanding#
Quick check
What is fast mode on Fable 5.2?
Show answer
Answer: The same model generating up to 2.5x faster at twice the per-token price
Anthropic lists fast mode at $16 / $80 per 1M tokens against $8 / $40 standard.
Short answers#
What is the API id? claude-fable-5-2.
What does it cost? $8 per 1M input and $40 per 1M output tokens; fast mode $16 / $80 (Anthropic, 9 November 2026).
Where can I use it? The Claude Platform, AWS, Google Cloud and Microsoft Azure; fast mode in Claude Code, the Claude Platform, Google Cloud and Microsoft Foundry.
What's Mythos 5.2? The same underlying model with weaker restrictions, for organisations approved through Anthropic's verification programs.


